Opening one port to the Internet — everything we found first
Context
For most of this homelab's life, the portal — documentation, a self-service catalog, an admin panel, and more recently a small chatbot answering questions about the lab — only existed on the inside, behind an ISP box that let essentially nothing in from the Internet. That was fine while the portal was a project, not a product.
Then it became worth showing to people who aren't me. That meant putting something on the public Internet, on a name that sits outside the internal-only DNS suffix every other homelab service lives under. We had a spare public IP and no CGNAT, so the obvious move was a port forward straight to a reverse proxy, rather than a tunnel through a third party. The goal was to expose exactly one thing: the public-facing part of the portal. Everything else — the wiki, the git server, the project tracker, the automation platform, the internal identity provider, the hypervisor UI — needed to stay exactly as unreachable as it already was.
One rule before touching anything: prove each piece of the chain works and is safe, in isolation, before the first packet from the Internet is allowed to reach it. That rule is basically the whole story below.
What we found before opening the door
None of this was on the original checklist. It's what turned up while actually trying to satisfy that one rule, rather than trusting a reasonable-looking plan.
1. The firewall's own admin interface was reachable from WAN
Before anything else, I checked what the firewall itself was listening on — not the rules it enforces, but its own web admin. It was bound to every interface, including the WAN side about to become Internet-facing. That's the one interface that should never see it. Fixed to LAN-only, with HSTS turned on for the page itself. A route to it existing at all on WAN was the exposure, independent of any NAT rule.
2. Dynamic DNS "worked" — then lied about it, quietly, forever
The dynamic DNS client updated the public record fine the first time. After that, its log filled with "no global IP detected," every five minutes, indefinitely. Cause: the detection method configured was "read it off the interface," which fails behind double NAT, because the firewall's own WAN address is itself private — the real public address only exists one hop further out, on the ISP box.
Fixed by switching detection to an external web service that answers "what address did this request come from," instead of reading a local interface. Proven, not assumed: I forced the DNS record at the registrar to a bogus address and watched it get corrected in under a minute. The lesson outlives the DNS specifics: a log that stays quiet on success isn't evidence of success, only of silence — the state file, not the log, was the only thing telling the truth.
3. The firewall itself wasn't current, and the update kept failing
Before exposing anything, the firewall needed a current base system. The update kept failing partway through. Root cause, found by watching the transfer rather than reading an error string: the updater fetched the ~134 MB main package in about eight seconds without issue, then fetched a signature file a few kilobytes in size — and that tiny fetch hit a fixed download timeout and got killed before it could finish, a bug in how that timeout was applied by the installed base's fetch tool. The bytes weren't the problem; the deadline was.
Workaround: strip the timeout from the updater's own wrapper script, run the update once, restore the wrapper. The bug lived entirely in the old base — the new base's updater didn't reproduce it. A one-time detour, not a permanent patch.
4. The intrusion-prevention agent was running, and blind to HTTP
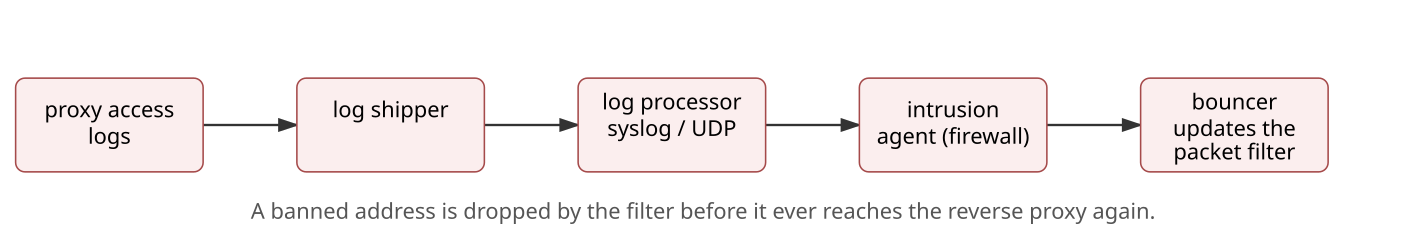
CrowdSec (an agent that reads logs, recognizes attack patterns, and can trigger a ban) was already installed on the firewall, but fed only the firewall's own logs and community threat lists — nothing about what was actually happening at the HTTP layer, which is where a public web app gets probed. I built the missing chain: the reverse proxy's access logs get shipped by a log shipper to the log-processing host, which re-emits a subset as syslog over UDP toward CrowdSec on the firewall, which drives a "bouncer" — the component that updates the packet filter when a ban is decided.
Two traps here. First, the log host had no route to the DMZ segment where the firewall's relevant interface lives — traffic went nowhere until a route was added and made permanent, not just poked in by hand. Second, and costlier: I'd been asked to move that syslog feed from UDP to TCP, since UDP is easier to spoof than TCP on an interface about to be Internet-adjacent — a reasonable ask on its own. I implemented it, tested it, then found, reading the tool's source rather than trusting its documented config schema, that its syslog listener is hard-wired to UDP — the protocol field exists but is never wired to anything else. Full revert. What that detour was worth keeping: it settled how urgent the spoofing risk actually was. The address a future public NAT rule forwards to is the firewall's WAN address, which is not the address CrowdSec's syslog listener is bound to — so that feed was never reachable from the Internet regardless.
Validated with a real test, not a synthetic one: from a short-lived, self-service-provisioned throwaway VM, on a segment where the only path to the exposed proxy is the same one a real visitor would take, I generated traffic meant to trip a ban. It did — the agent parsed the feed, raised an alert, issued a temporary ban the firewall enforced, and released the address once the test window closed.
5. The exposed proxy also fronted the guest identity provider, with no brute-force protection
The same reverse proxy that would carry public traffic to the portal also fronted the identity provider used for outside-visitor accounts, on the same box for unrelated reasons. That provider had no brute-force lockout configured. Rather than harden it under time pressure and hope, the decision was simpler: don't expose those paths under the public name at all. Anything under that identity path now returns a generic "not found" on the public name — the access-request flow visitors need doesn't touch it. Brute-force detection was enabled on it afterward regardless, as defense in depth, not as the primary control.
6. An SSH host key changed — and it wasn't an attack
During a routine pre-opening security check, connecting to the guest identity provider host revealed its SSH host keys had changed — both key types at once, a much stronger signal than one new key type being added. Connections stopped immediately and the event was flagged as a possible compromise, on a machine being prepared, at that exact moment, for public exposure. The right call, even though it was a false alarm.
Verification happened entirely out of band: rather than trust anything the machine might say over a network connection that could be intercepted, its disk was read directly from the hypervisor, without booting it or touching the network. The host keys on disk were all timestamped to the same minute as a VM restart triggered the day before by an infrastructure-as-code apply — a DNS setting change that, by design, requires a restart to take effect. That restart made the guest OS's first-boot tooling treat it as a "new instance" and regenerate its host keys, expected behavior for that tooling, not a bug. Legitimate — but it exposed something worth fixing regardless: SSH host-key checking had been left disabled in that repository's connection settings, so a real key swap would have been accepted just as silently as this legitimate one was investigated loudly. Fixed, and not just there — the same setting was audited and hardened across every repository in the homelab that opens an SSH connection.
7. A security alert that had never once fired
While building an operational dashboard for the exposed proxy's traffic, I checked whether an existing alert — meant to catch access attempts on sensitive, supposedly blocked paths — had ever triggered. It never had, since the day it was created, despite real attempts against those exact paths sitting in the logs the whole time. Two compounding causes: its list of sensitive paths covered only five of the eight actually blocked, and — the same mistake twice, at two layers of the same system — its filter matched the full-text-analyzed version of the path field instead of the exact-match version, so even the five it knew about mostly didn't match. The identical mistake independently broke four panels of the new dashboard and its map, because the log index behind them relied on Elasticsearch guessing each field's type from whatever value arrived first, rather than a type declared up front. Fixed with an explicit mapping template, applied before fresh data arrived rather than after.
That wasn't quite the end of the thread. A later round of debugging found a dashboard map panel silently referencing an internal layer-type name a platform upgrade had since renamed — the saved object was old enough that the automatic migration for it never re-ran, because the version tag on the export it came from read as newer than the version the rename shipped in, so the migration logic skipped it as "already current" when it wasn't. Fixed by hand-correcting the stale field and reimporting. Three rounds of fixing the same dashboard in one day, each catching a different failure mode: a server-side data problem, a client-side config that never reached the server, and a stale reference nobody restated correctly.
Why the design looks the way it does
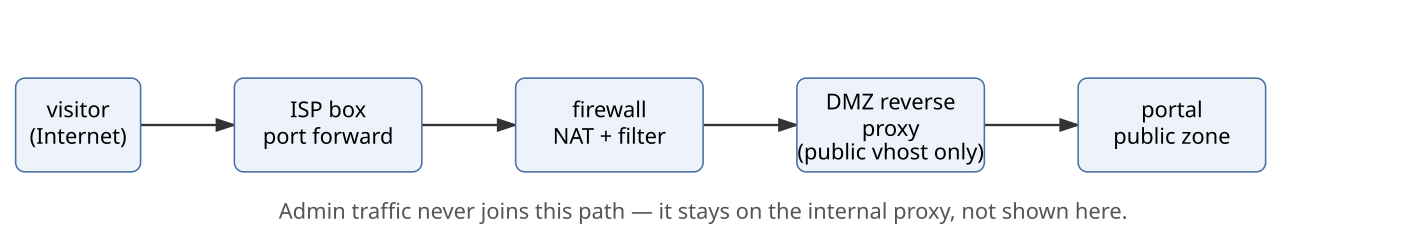
Two paths exist through this setup, on purpose. Administration goes through the reverse proxy that has always sat inside the network, and never touches the one facing the Internet. Visitors reach only the second one, which only knows how to reach the public zone of the portal — nothing else exists to it. That split predates this write-up: routing every internal service off the same reverse proxy by hostname, on one shared certificate, meant exposing that proxy to the Internet would have exposed everything behind it at once, since routing-by-hostname doesn't care which network a request came from. A dedicated, narrowly-scoped proxy for the public path avoids that entirely.
I forwarded a single port rather than declaring the whole reverse-proxy host as the ISP box's "exposed host" — a blunter option that forwards everything to one internal address. That option never actually took effect on this box without a full reboot of the box itself, which alone made it worse operationally. It's also looser by nature: a single forwarded port names exactly one destination address and port, nothing implicit.
One detail worth stating plainly: NAT and filter rules are two separate layers, and both must be widened together. Forgetting the filter half — leaving the NAT translation in place without a matching pass rule — produces a connection that starts and then times out, which looks confusingly like "nothing is listening" rather than "something is silently dropping this." It's an easy trap precisely because the failure mode gives so little information about which layer is missing.
A note on who does what: throughout all of this, agents did the finding, the building, and — more than once — the refusing to proceed when something looked wrong. The decision to actually flip a control that makes the lab reachable from the Internet, and the literal typing of commands on the firewall itself, stayed with me. No agent has shell access to that box. That's not a trust statement about the agents specifically; it's a line drawn around anything that turns "isolated" into "reachable," on principle.
Diagram — request path
Opening it, in about ten minutes
Once every piece above was proven in isolation, actually opening the door was almost anticlimactic: widen the NAT rule, widen the matching filter rule right after it, list the active filter rules to confirm both took effect exactly as written, declare the forwarded port on the ISP box, then test from a connection that isn't on the LAN at all — a phone on mobile data, not Wi-Fi — checking that a blocked path returns "not found" and that the operational dashboard shows the test traffic arriving. Every step has a one-line undo: pull the NAT rule, or the filter rule, or the port forward on the box, and the whole thing goes back to unreachable from outside, immediately.
Diagram — log path to a ban
Epilogue
The public name went live at roughly 16:45 on the second day. The first scanner — a generic HTTP client probing for exposed configuration and secrets files — was banned by the intrusion-prevention chain at 17:37, 53 minutes after opening, with an email notification as proof the notification path worked too, not just detection. Separately, a search engine crawler found the site within minutes of the first real visit from a phone — faster than I expected an unannounced address to get noticed at all.
Also on a phone: the homepage's interactive 3D scene didn't render at all on mobile, first time out. The cause wasn't the obvious suspects — not CSS, not a JavaScript error at load, not a reduced-motion setting. It was a GPU context getting silently dropped under real mobile memory pressure, after rendering had already started successfully, with nothing in place to notice that had happened and recover. Fixed with a listener for exactly that event and a lighter static fallback for when it fires.
Lessons
Nothing gets opened before it's proven, not assumed. Every test that matters runs from outside the LAN, because that's the only vantage point that actually matches a real visitor. A log that says nothing is not the same as a log that says everything is fine. An alert that has never once fired is not evidence of a quiet system — it might just be an alert that was broken from the day it was written. An infrastructure change that looks like "one field" can restart production without anyone deciding to restart anything. And opening one door mostly means discovering everything it was quietly protecting, sight unseen, until that exact moment.
None of the above is the full picture, and it isn't meant to be — some things about this network stay off this shelf on purpose. I'd rather say so plainly than let a reader wonder: see what this shelf does not show for what's left out, and why.